EN PL DE
Contact sales

AI infrastructure partner · EU

Infrastructure for the age of AI.

GPU cloud, NVIDIA-based hardware and turnkey AI environments — designed, sourced and deployed by one partner, across Europe.

EU company — delivery and invoicing across the European Union
Full NVIDIA stack — from GeForce RTX to Blackwell Ultra
From a single workstation to a rack-scale AI factory
One partner: consulting, supply, deployment, support

What we do

Three ways to get compute. One partner.

Rent it, buy it, or have it built. GTECH AI covers the full path from the first GPU to a production AI environment.

Scale

From one GPU to an AI factory.

Every tier is available to rent, to buy, or as a fully deployed environment. Start where you are — scale without changing partner.

01

Workstation

Local development, prototyping and inference for individuals and small teams.

  • GeForce RTX 5090 · RTX PRO 6000
  • NVIDIA DGX Spark · DGX Station
  • 1–4 GPUs per seat

02

Server

Production training and inference for a department or a product.

  • HGX B200 / B300 8-GPU systems
  • NVIDIA DGX B300
  • RTX PRO 6000 Server Edition nodes

03

Cluster

Multi-node training with InfiniBand or Spectrum-X fabric and parallel storage.

  • Dozens to hundreds of GPUs
  • NVIDIA Quantum-X800 InfiniBand
  • Slurm or Kubernetes scheduling

04

Data centre

Rack-scale, liquid-cooled AI factories for frontier workloads.

  • NVIDIA GB200 / GB300 NVL72
  • NVIDIA DGX SuperPOD
  • Vera Rubin NVL72 (from H2 2026)

Featured hardware

Built on NVIDIA. Available across Europe.

A selection of the platforms we supply and deploy. Specifications per NVIDIA documentation; configurations on request.

Consumer flagship

GeForce RTX 5090

Blackwell-architecture flagship for local AI development, rendering and inference.

  • Memory32 GB GDDR7
  • CUDA cores21,760
  • Power575 W
Learn more – GeForce RTX 5090

Workstation & server

RTX PRO 6000 Blackwell

96 GB of ECC memory for large models on the desk or in a rack — Workstation, Max-Q and Server Editions.

  • Memory96 GB GDDR7 ECC
  • Power300–600 W
  • InterfacePCIe Gen 5 x16
Learn more – RTX PRO 6000 Blackwell

Desktop AI supercomputer

NVIDIA DGX Spark

Petaflop-class AI on your desk — run and fine-tune models of up to 200 billion parameters locally.

  • SuperchipGB10 Grace Blackwell
  • Unified memory128 GB
  • AI performance1 PFLOP FP4
Learn more – NVIDIA DGX Spark

Desktop AI supercomputer

NVIDIA DGX Station

Grace Blackwell Ultra desktop superchip for models of up to a trillion parameters — data-centre class, under a desk.

  • GPU memory252 GB HBM3e
  • CPU memory496 GB LPDDR5X
  • AI performance20 PFLOPS FP4
Learn more – NVIDIA DGX Station

8-GPU platform

NVIDIA HGX B300

Eight Blackwell Ultra GPUs with 2.1 TB of HBM3e — the building block for training and reasoning inference at scale.

  • GPUs8× Blackwell Ultra
  • GPU memory2.1 TB HBM3e
  • FP4 inferenceup to 144 PFLOPS
Learn more – NVIDIA HGX B300

Rack-scale AI factory

NVIDIA GB300 NVL72

72 Blackwell Ultra GPUs and 36 Grace CPUs in one liquid-cooled rack that acts as a single giant GPU.

  • GPUs / CPUs72 / 36
  • GPU memory20 TB HBM3e
  • NVLink bandwidth130 TB/s
Learn more – NVIDIA GB300 NVL72

Specifications per NVIDIA product documentation, September 2026. Availability and lead times depend on configuration and allocation.

How we work

A clear path from requirement to running workload.

Five steps, each with a deliverable and a decision point — whether you rent a GPU or build a data hall.

01

Discover

We map your workloads, models, data and constraints — and define what success looks like.

Deliverable: requirements & sizing model

02

Design

Architecture and TCO: cloud, on-prem or hybrid, with a bill of materials you can sign off.

Deliverable: architecture & itemised offer

03

Source

Procurement through authorised channels, transparent pricing, EU logistics and customs handled.

Deliverable: configured, tested systems

04

Deploy

Installation, cabling, software stack and validation — handed over with documentation and benchmarks.

Deliverable: running, documented environment

05

Support

Monitoring, updates, capacity planning and expansion — as an SLA-backed service.

Deliverable: defined response times

Why GTECH AI

Engineering first. Trading second.

We are an infrastructure company that sells hardware — not a reseller that occasionally configures it.

Workload-driven sizing

We size GPUs, memory, network and storage from your actual models and throughput targets — not from a price list.

EU-based, EU-compliant

Polish company, EU VAT, invoicing and delivery across the Union. Cloud services in EU data centres with GDPR-ready processing.

Full stack, validated as a whole

NVIDIA GPUs, NVIDIA-Certified systems, NVIDIA networking and the software that ties them together — tested before handover.

Rent, buy or hybrid

Start in the cloud, move on-prem when utilisation justifies it — same partner, same architecture, no migration surprises.

Transparent pricing

Itemised offers, real lead times, no hidden fees. You see exactly what you pay for.

Support that stays

The engineers who design your environment are the ones who support it afterwards.

Real deployments

Deployed, not rendered.

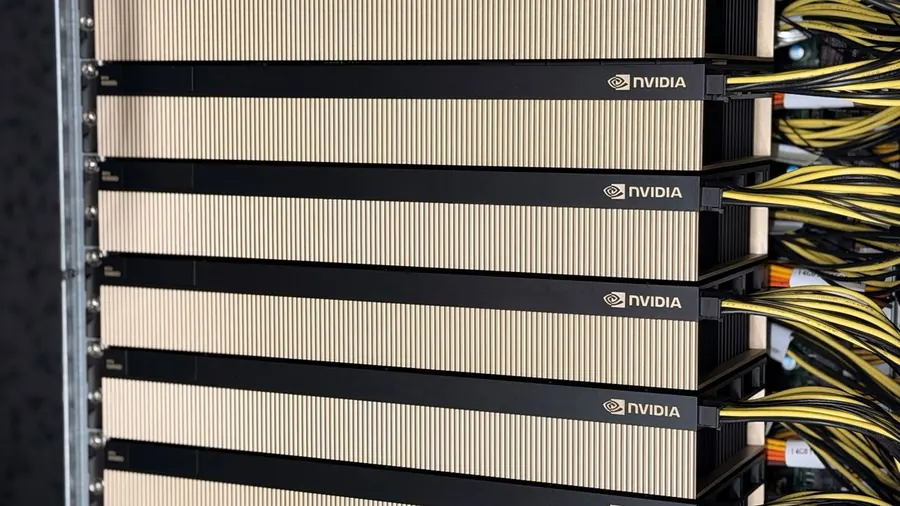
A few photos from racks we have built, filled and commissioned — GPU nodes, storage, fabric and the work in between.

Use cases

Where our customers run AI.

LLM training & fine-tuningMulti-GPU and multi-node training with InfiniBand fabric and fast parallel storage.
Inference & AI agentsLow-latency serving with TensorRT-LLM, vLLM and NVIDIA NIM microservices; FP4 on Blackwell.
Computer visionQuality inspection, video analytics and robotics pipelines at the edge and in the data centre.
Research & HPCSimulation, scientific computing and university clusters with Slurm scheduling.
Media & renderingGenerative video, 3D rendering and virtual production on RTX PRO and GeForce RTX.
Industry & manufacturingPredictive maintenance, digital twins and on-prem AI where data cannot leave the site.

Let's talk

Tell us what you want to run. We'll tell you what it takes.

Share your workload, timeline and budget — you will get an architecture proposal and an itemised offer, not a sales pitch.

Enquiries answered in English, Polish and German.