GeForce RTX 50 Series
Consumer Blackwell GPUs for developers, creators and small inference deployments.
GeForce RTXAI Hardware
From the most powerful consumer graphics cards to rack-scale Blackwell Ultra systems: we source, configure, deliver and commission NVIDIA-based AI hardware for companies across Europe.
Portfolio
Six product families, one supplier — with configuration, delivery and commissioning included where you need it.
Consumer Blackwell GPUs for developers, creators and small inference deployments.
GeForce RTXProfessional GPUs with ECC memory for workstations and servers — up to 96 GB.
RTX PROHopper and Blackwell accelerators: H100, H200, B200 and B300.
Hopper & BlackwellTurnkey AI supercomputers from DGX Spark to DGX B300 and SuperPOD.
DGX8-GPU baseboards and rack-scale GB200/GB300 NVL72 AI factories.
HGX & NVL72NVIDIA InfiniBand and Spectrum-X, AI storage, NVIDIA-Certified servers and components.
Fabric & dataConsumer & prosumer
Blackwell-architecture consumer GPUs for developers, creators and small inference deployments — the fastest way to get CUDA on a desk. Available individually, in volume, or built into ready-to-run workstations.
Flagship
The most powerful consumer GPU: local LLMs, diffusion models, rendering and simulation.
High-end
High-end development and inference at a lower power budget.
Built to order
Custom workstations with 1–4 GPUs, high-core-count CPUs, ECC memory and NVMe storage — delivered with drivers and CUDA ready to use.
Full GeForce RTX 50 line-up (RTX 5070 – RTX 5090) available on request, including volume orders for labs and studios.
Professional
Professional Blackwell GPUs with ECC memory, certified drivers and multi-GPU support — for workstations and servers running AI, simulation, rendering and virtual workstations.
Workstation Edition
The largest-memory workstation GPU: run 100B+ parameter models locally, fine-tune, render and simulate.
Max-Q Workstation Edition
The same 96 GB at 300 W — for dense multi-GPU workstations and quieter environments.
Server Edition
Passively cooled for 1–8 GPU servers: inference, video, VDI and mixed enterprise AI workloads.
| Model | Memory | Max power | Form factor |
|---|---|---|---|
| RTX PRO 6000 Blackwell Workstation Edition | 96 GB GDDR7 ECC | 600 W | Dual slot, active |
| RTX PRO 6000 Blackwell Max-Q | 96 GB GDDR7 ECC | 300 W | Dual slot, active |
| RTX PRO 6000 Blackwell Server Edition | 96 GB GDDR7 ECC | 400–600 W | Dual slot, passive |
| RTX PRO 5000 Blackwell | 48 GB GDDR7 ECC | 300 W | Dual slot, active |
| RTX PRO 4500 Blackwell | 32 GB GDDR7 ECC | 200 W | Dual slot, active |
| RTX PRO 4000 Blackwell | 24 GB GDDR7 ECC | 140 W | Single slot, active |
Power figures are NVIDIA's maximum board power. All models: PCIe Gen 5 x16, 4× DisplayPort 2.1 (Server Edition: headless option).
Field-proven
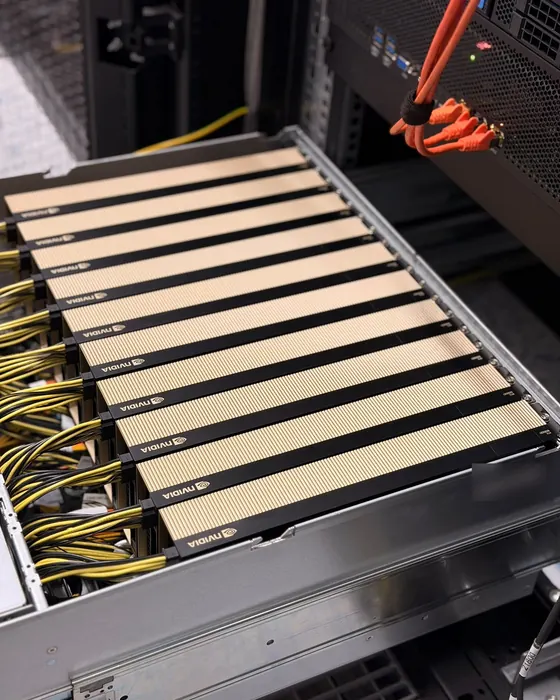
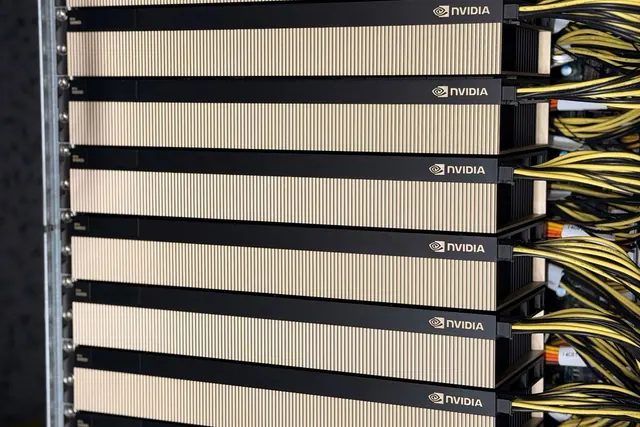
The photo shows a production node from one of our deployments: ten NVIDIA RTX PRO 6000 series Server Edition GPUs — 960 GB of GDDR7 ECC memory — in a single 4U air-cooled chassis with PCIe Gen 5.
Dense RTX PRO nodes are the sweet spot for inference, vision and rendering farms: high memory per euro, standard air cooling and OEM chassis available from stock.
Data-centre GPUs
The accelerators behind today's AI factories — supplied as modules, in HGX baseboards or as complete NVIDIA-Certified servers.
Hopper
The Hopper GPU with the most memory — ideal for large-model inference and memory-bound training.
Blackwell
Second-generation Transformer Engine with FP4 and fifth-generation NVLink — the Blackwell workhorse for training and inference.
Blackwell Ultra
1.5× the dense FP4 compute of Blackwell and more HBM3e per GPU — built for AI reasoning at scale.
| GPU | Architecture | Memory | Memory bandwidth | Interconnect |
|---|---|---|---|---|
| NVIDIA H100 SXM | Hopper | 80 GB HBM3 | 3.35 TB/s | NVLink 900 GB/s |
| NVIDIA H200 SXM | Hopper | 141 GB HBM3e | 4.8 TB/s | NVLink 900 GB/s |
| NVIDIA B200 | Blackwell | 180 GB HBM3e | up to 8 TB/s | NVLink 1.8 TB/s |
| NVIDIA B300 | Blackwell Ultra | up to 288 GB HBM3e | up to 8 TB/s | NVLink 1.8 TB/s |
Per-GPU figures per NVIDIA documentation; HGX B200 / B300 8-GPU totals: 1.4 TB / 2.1 TB HBM3e.
NVIDIA DGX
Integrated systems designed by NVIDIA, delivered and commissioned by us — from a desktop unit to a SuperPOD.
Desktop
GB10 Grace Blackwell Superchip with 128 GB of unified memory: develop, fine-tune and run models of up to 200B parameters on a desk.
Desktop
GB300 Grace Blackwell Ultra Desktop Superchip — data-centre-class performance for models of up to a trillion parameters, under a desk.
Rack
Eight Blackwell Ultra GPUs, integrated NVIDIA networking and NVIDIA AI Enterprise software — the enterprise building block of DGX SuperPOD.
NVIDIA DGX SuperPOD (with DGX B300 or GB300 NVL72) designed and delivered according to NVIDIA reference architectures — ask us for a scoping call.
Rack scale
For the largest training and inference workloads: 8-GPU HGX baseboards in NVIDIA-Certified servers, and liquid-cooled GB200/GB300 NVL72 racks that act as one giant GPU.
8-GPU platform
Eight Blackwell GPUs with 1.4 TB of HBM3e in a range of OEM servers — air or liquid cooled.
8-GPU platform
Eight Blackwell Ultra GPUs with 2.1 TB of HBM3e and 1.6 TB/s of networking — built for reasoning-era inference and training.
Rack-scale
72 Blackwell Ultra GPUs and 36 Grace CPUs in one liquid-cooled rack — 20 TB of HBM3e connected by 130 TB/s of NVLink.
| System | GPUs | GPU memory | NVLink | Cooling |
|---|---|---|---|---|
| NVIDIA HGX B200 | 8× Blackwell | 1.4 TB HBM3e | 14.4 TB/s | Air or liquid |
| NVIDIA HGX B300 | 8× Blackwell Ultra | 2.1 TB HBM3e | 14.4 TB/s | Air or liquid |
| NVIDIA GB200 NVL72 | 72× Blackwell + 36× Grace | 13.5 TB HBM3e | 130 TB/s | Liquid |
| NVIDIA GB300 NVL72 | 72× Blackwell Ultra + 36× Grace | 20 TB HBM3e | 130 TB/s | Liquid |
| NVIDIA Vera Rubin NVL72 | 72× Rubin + 36× Vera | 288 GB HBM4 per GPU | next-gen NVLink | Liquid |
Vera Rubin: NVIDIA has announced production hardware for partners in the second half of 2026 — talk to us about roadmap planning and early allocation.
Fabric & data
A GPU is only as fast as the data reaching it. We deliver the fabric, the storage and the NVIDIA-Certified servers around the accelerators — and the components to keep them running.
NVIDIA networking
Quantum-X800 InfiniBand and Spectrum-X Ethernet switches, ConnectX-8 SuperNICs and BlueField-3 DPUs — the fabric for multi-node training.
AI storage
All-NVMe and parallel file systems sized for datasets and checkpoints; S3-compatible object storage for archives.
NVIDIA-Certified
GPU servers from leading OEMs such as Supermicro, ASUS, GIGABYTE, Dell Technologies, HPE and Lenovo — validated for NVIDIA GPUs and networking.
Components
Server CPUs, ECC and HBM memory, NVMe drives, power supplies and GPU risers for upgrades, expansions and repairs.
Storage
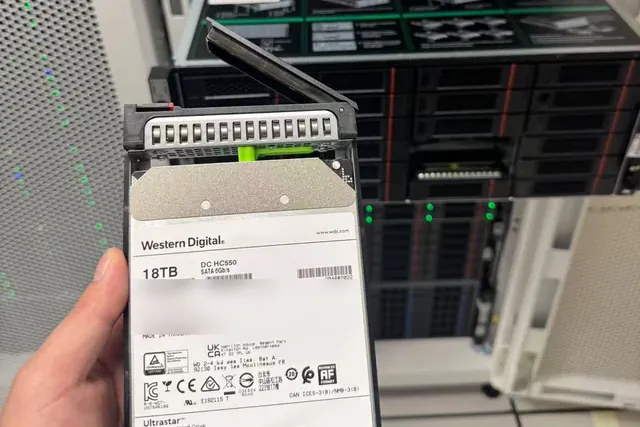
High-capacity HDD arrays for datasets and archives, all-NVMe for checkpoints and hot data — assembled, burn-in tested and delivered together with the rest of the cluster.
Supply & logistics
Hardware sourced through authorised distribution with full manufacturer warranty and EU-valid serial numbers.
Insured shipping to any EU country — to the loading dock or into the rack — with customs handled for destinations outside the Union.
Itemised quotes with lead times and validity; volume and framework agreements for repeat buyers.
Purchase, leasing or rental — we help match the model to your project's cash flow.
Systems assembled, updated and stress-tested before delivery; optional on-site installation.
Upgrade paths as new NVIDIA generations arrive; spare parts and RMA handling for the life of the system.
In the field
FAQ
Yes — we invoice and deliver across the European Union (intra-community supply with your EU VAT ID) and can arrange export beyond the EU.
Consumer and workstation GPUs: usually from stock or within days. HGX and DGX systems: several weeks depending on configuration and NVIDIA allocation. NVL72 racks: project-based. We state real lead times in every offer.
Yes. We configure, assemble, update firmware, install the software stack and burn-in test before shipping — or commission the system on site.
Yes: warranty handling, RMA, spare parts and optional support contracts with defined response times.
For most GPU classes you can benchmark your workload in our cloud first — see Cloud AI.
Quote
Send us the model, quantity and target delivery date — or just the workload, and we will propose the configuration.