Assessment & sizing
Workload analysis, model and data profiling, throughput targets, GPU/memory/network sizing and TCO comparison: cloud vs on-prem vs hybrid.
AI Infrastructure
From workload assessment to a validated, documented and supported AI cluster: we design and build on-premises and hybrid environments on NVIDIA technology — and stay to operate them.
Scope
Workload analysis, model and data profiling, throughput targets, GPU/memory/network sizing and TCO comparison: cloud vs on-prem vs hybrid.
Designs based on NVIDIA reference architectures: compute nodes, NVLink domains, InfiniBand or Spectrum-X fabric, storage tiers, management network.
Rack power planning, PDUs, UPS coordination, air or direct liquid cooling for Blackwell-class density — with your facility team or ours.
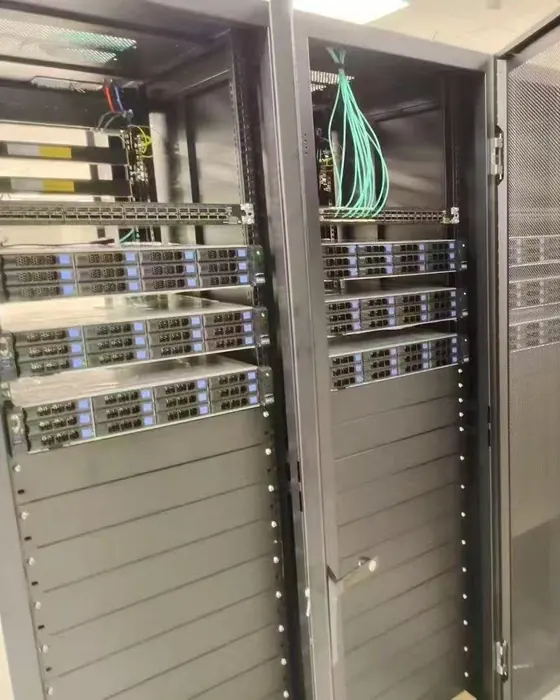
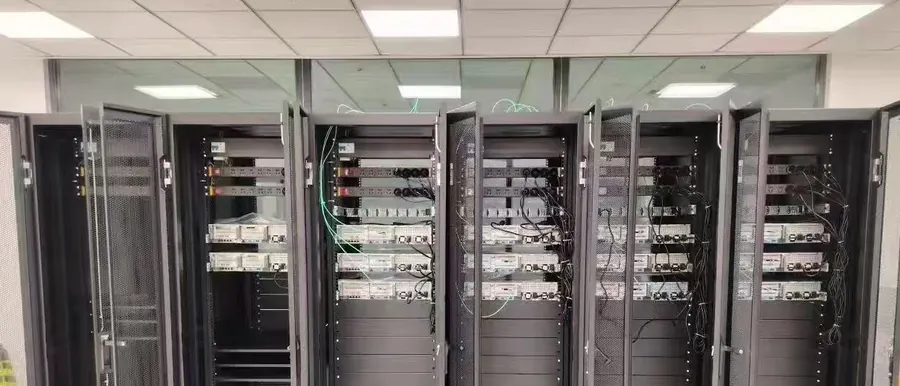
Rack integration, structured cabling, optics and fibre for InfiniBand and Ethernet — labelled and documented.
OS, drivers, CUDA, container runtime, NVIDIA AI Enterprise, Kubernetes with GPU Operator or Slurm — installed, hardened and versioned.
Experiment tracking, pipelines, model registry and serving (MLflow, Kubeflow, NVIDIA NIM), plus multi-tenant scheduling for teams.
Burn-in, NCCL and storage tests, reference-model benchmarks — you get numbers, not promises, at handover.
Network segmentation, access control, secrets management and documentation supporting ISO 27001 and GDPR requirements.
Monitoring (DCGM, Prometheus), updates, capacity planning, expansion and SLA-based support after go-live.
Deployment tiers
The same method applies at every scale; only the components change.
01
Single-user AI workstations and DGX Spark / DGX Station rollouts for teams starting with local models.
02
One or a few GPU servers in your server room — inference platforms and departmental training.
03
Multi-node clusters with high-speed fabric, parallel storage and job scheduling for ML teams and research.
04
Rack-scale, liquid-cooled deployments and SuperPOD-class installations with full facility planning.
Process
Workshops with your data science, IT and facilities teams to capture workloads, growth plans, data flows and constraints.
Detailed architecture and bill of materials, validated against NVIDIA reference designs and your facility.
Procurement of all components through authorised channels, with staging and pre-assembly before delivery.
On-site installation, cabling, network and storage configuration, software deployment and acceptance testing.
Ongoing operations: monitoring, updates, incident response and capacity planning as an SLA-backed service.
Deliverables
From our deployments
Industries
FAQ
We model both. As a rule of thumb, sustained utilisation over a multi-year horizon favours ownership; bursty or uncertain demand favours cloud. Because we offer both, the recommendation is not biased towards either.
For HGX B300 and NVL72 systems direct liquid cooling is the standard; air-cooled options exist for many 8-GPU and RTX PRO servers. We assess your facility and design accordingly.
Yes. We integrate with your facility team or colocation provider and can also recommend EU colocation sites suited to high-density AI racks.
Ubuntu or RHEL-based nodes, NVIDIA drivers and CUDA, container runtime, Kubernetes with NVIDIA GPU Operator or Slurm, NVIDIA AI Enterprise where licensed, plus monitoring and MLOps tooling agreed with your team.
Yes — from warranty handling to SLA-backed operations with monitoring, patching and capacity planning. The engineers who built the environment support it.
Assessment
A short workshop and a sizing model tell you what your workloads really need — before you commit to hardware.